
Building an AI Landing Zone on Azure — Part 2: The platform underneath
Before the gateway and the metering there is a private AKS cluster, a hub-and-spoke network and a GitOps setup where no application ever holds a secret. This is how that foundation is put together.
This is part 2 of a five-part series on building an AI Landing Zone on Azure. Part 1: Why every enterprise needs an AI gateway · Part 2: The platform underneath (this post) · Part 3: One front door for many models · Part 4: Metering every call · Part 5: Turning tokens into euros
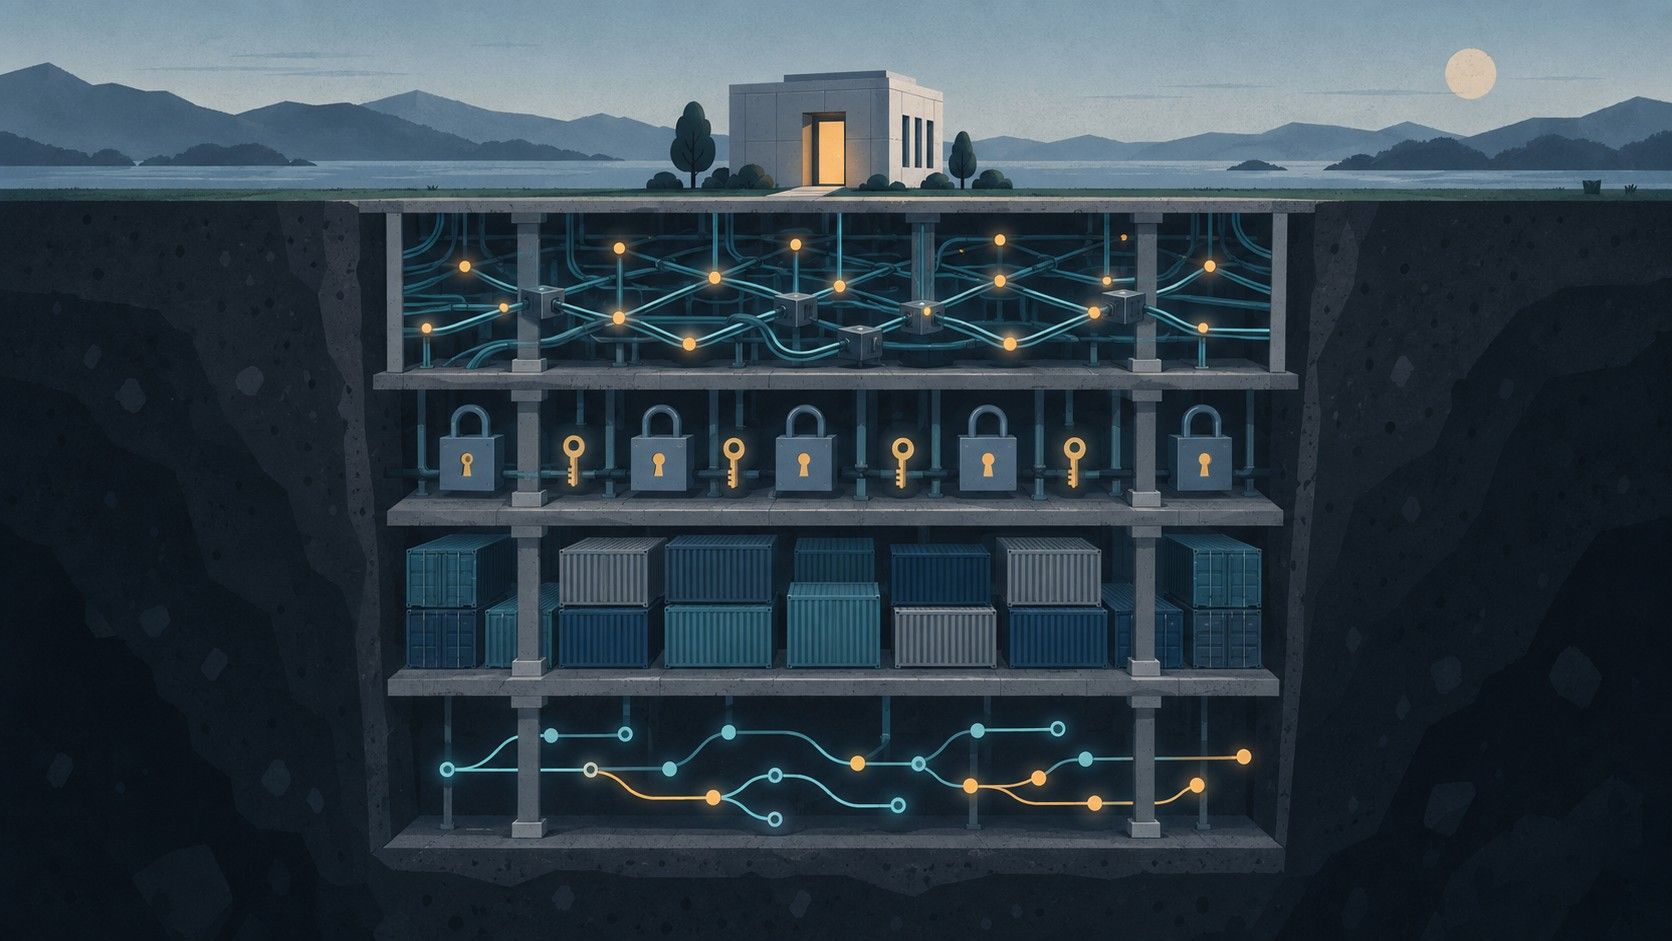
In part 1 I described the shape of the AI Landing Zone I built for a regulated insurer and the principles behind it. Before I get to the interesting AI-specific parts, I need to cover the foundation, because the gateway and the metering pipeline only work the way they do because of decisions made down here. If you have built Azure landing zones before, some of this will be familiar; the AI-specific twist is mostly in how far the "no secrets, private everything" principle is pushed.
Network: a spoke with a very strict door policy
The zone is a single spoke VNet per environment, connected to the Virtual WAN hub. Internet security is enabled on the hub connection, which means all egress from the spoke is forced through the hub Azure Firewall. The firewall is also the VNet's DNS server, so private DNS resolution for all the private endpoints is handled centrally rather than per-spoke.
Inside the spoke there are seven subnets, each with a single purpose:
| Subnet | Purpose |
|---|---|
snet-apim |
APIM VNet injection |
snet-appgw |
Application Gateway (the only subnet with a route to the internet) |
snet-app |
AKS nodes |
snet-db |
PostgreSQL Flexible Server (delegated) |
snet-fn |
Function App VNet integration (delegated) |
snet-plink |
Every private endpoint in the zone |
Every subnet gets its own NSG. Each NSG has specific allow rules for what that subnet legitimately needs, such as the APIM subnet reaching Entra ID, Event Hub, Key Vault and Azure Monitor, or the database subnet accepting connections from the app and gateway subnets, and then a deny-all inbound and deny-all outbound at priority 4096. Remember by default, all traffic within a VNet is allowed with priority 65000 which breaks the zero-trust principle we want to maintain. The one exception is the Application Gateway subnet, where the default deny breaks the platform's own management traffic (default rule with priority 65001 is in place for that but never reached); I learned that one the hard way and left a comment in the code so nobody "fixes" it back.
Route tables send everything from the app, database, function and APIM subnets to the firewall as next hop. The Application Gateway is a Private Deployment (https://learn.microsoft.com/en-us/azure/application-gateway/application-gateway-private-deployment) and therefor is also routed to the firewall. You need to register the feature to make this work:
az feature register --name EnableApplicationGatewayNetworkIsolation --namespace Microsoft.NetworkThe practical consequence of all this is that nothing in the zone can talk to anything unless explicitly allowed. That is exactly what you want for a compliant workload.
AKS: private, Cilium, and no node pools to manage
The cluster is a private AKS cluster running Azure Linux 3 on every node. I picked Azure Linux over Ubuntu for the smaller footprint and because Microsoft maintains the image end to end, which matters for the patching story in a regulated environment.
Networking is Azure CNI in overlay mode with Cilium as both the network policy engine and the data plane, with Advanced Container Networking Services enabled for observability and security (this enables Hubble). Outbound type is user-defined routing, so node egress goes through the hub firewall like everything else; there is no NAT gateway or load balancer outbound path to worry about.
The cluster has the OIDC issuer and workload identity enabled. This is the single most important setting on the cluster for this project, and I will come back to it below.
For compute I made a deliberate choice to lean on node auto-provisioning (Karpenter) rather than static node pools. There is a small system node pool for critical add-ons, and a default pool that starts at zero nodes. Karpenter owns everything else, driven by a single NodePool that says: E-series, on-demand, amd64, at least four vCPUs and eight gigabytes, and consolidate empty nodes after thirty minutes. The workloads that run here are memory-hungry document processors that are bursty by nature, so paying for idle nodes made no sense, and Karpenter does a much better job of picking the right SKU for a given pod shape than I would with a fixed pool.
One gotcha worth mentioning: when you combine Karpenter with Cilium you must add the Cilium startup taint to the node template, otherwise pods get scheduled onto nodes before the Cilium agent is ready and they never get networking. It is documented, but it is easy to miss.
Diagnostics for the API server, audit logs and controllers go to Log Analytics, and Defender for Containers is wired to the same workspace. The Azure Policy add-on is on, though I keep policies in audit mode where Terraform owns the configuration, because a policy that mutates resources out-of-band gives you drift in your Terraform state.
GitOps: ArgoCD as the only way things get onto the cluster
Terraform builds the cluster and installs exactly two Helm charts: ArgoCD itself and the ArgoCD "apps" chart that bootstraps an app-of-apps. From that point on, Terraform never touches the cluster again. Everything that runs on it, whether that is cert-manager, external-dns, the ingress controller, VictoriaMetrics or the business applications, is defined in a separate Git repository and reconciled by ArgoCD.
The bootstrap uses ApplicationSets with a Git directory generator: every directory under charts/<namespace>/<chart> in the GitOps repository becomes an ArgoCD application, deployed into the namespace named by the path, with per-environment values files. Adding a new platform component is a directory and a merge request. There is also a separate ArgoCD project for merge-request preview environments, so developers get an ephemeral deployment of their branch without anyone touching production tooling. That is what makes ApplicationSets so powerful: it makes it very easy to deploy an entire application landscape in a short-lived branch.
ArgoCD's UI is behind Entra ID single sign-on with group claims. Admins, developers and readers are Entra groups, and the mapping to ArgoCD roles is in the Helm values. Nobody has an ArgoCD local admin password, because the admin user is disabled at install.
The reason I am strict about this split is auditability. The cluster's state is the Git history of one repository. If the risk department wants to know what changed in production last Tuesday, that question has a precise answer.
Ingress and certificates
Ingress is Application Gateway WAF v2 with the Application Gateway Ingress Controller (AGIC) running in-cluster. The WAF policy runs OWASP 3.2 plus the bot manager ruleset. Note that the Application Gateway fronts the applications on the cluster, not APIM; the AI gateway is only reachable from inside the private network.
cert-manager issues Let's Encrypt certificates with a DNS-01 challenge against the client's public DNS zone, and external-dns keeps the private DNS zone in sync with what is running on the cluster. Both need to write to DNS zones in other subscriptions, which brings me to the part that ties the whole platform together.
Workload identity: the applications never see a secret
Every controller and every application on the cluster that needs to talk to Azure does so through a user-assigned managed identity and a federated credential. The pattern is always the same and it is entirely in Terraform:
- Create a user-assigned managed identity for the component.
- Create a federated identity credential on it, with the cluster's OIDC issuer as the issuer and
system:serviceaccount:<namespace>:<serviceaccount>as the subject. - Assign that identity exactly the roles it needs, at the narrowest scope that works. This implements least-privilege.
The Kubernetes side is just a service account annotated with the identity's client ID. When a pod using that service account asks the Azure SDK for a token, the SDK exchanges the pod's projected Kubernetes token for an Entra ID token. No client secret, no certificate, nothing to rotate, nothing to leak.
Here is what that looks like in practice for this zone:
| Component | Identity gets |
|---|---|
| AGIC | Contributor on the Application Gateway, Reader on the node resource group, a custom "join VNet" role |
| cert-manager | DNS Zone Contributor on the public zone (in the shared subscription) |
| external-dns | Private DNS Zone Contributor |
| AKS Key Vault CSI | Key Vault Secrets reader on the workload's Key Vault |
| Any AI workload app (frontend + backend) | Key Vault Secrets User on its own Key Vault, Storage Blob Data Contributor on its own container |
Notice that each application gets two identities, one for the frontend and one for the backend, and each application gets its own Key Vault. That is more resources than strictly necessary, but it means the blast radius of a compromised frontend pod is one Key Vault and one storage container, and it means I can show a reviewer the exact permissions of any running process in a single table.
Where an application genuinely needs a secret at runtime, such as the connection string for its PostgreSQL database or an OAuth client secret for its own SSO, the CSI driver pulls it from Key Vault into a Kubernetes secret, again authenticated with workload identity. The secret is created by Terraform, stored in Key Vault, and read by CSI. At no point does anyone gets or needs access to the secrets.
The same principle carries across to the PaaS side. Storage accounts have shared key access disabled. Cosmos DB has local authentication disabled and is accessed through its data-plane RBAC roles. Event Hub is managed identity only. Key Vaults use RBAC authorisation with purge protection and 90-day soft delete. When I say "no shared keys anywhere" in part 1, this is what it means in practice: the option is turned off at the resource, so a future engineer cannot quietly turn it back on in an app setting.
Observability
Cluster-level diagnostics go to Log Analytics and Application Insights, and Network Watcher flow logs with traffic analytics are enabled on the VNETs, which is unmissable if you want to do proper zero trust in your VNet. Without VNET flow logs, I would have never found out that even inter-cluster traffic (over the cluster CIDR) is also subject to NSGs. Inside the cluster, VictoriaMetrics handles metrics, logs and traces. I went with VictoriaMetrics over Azure Monitor managed Prometheus mainly for cost and control: the usage pipeline in part 4 pushes token metrics straight into it, and a Grafana dashboard on top gives the platform team a live view of gateway traffic without waiting for a Power BI refresh.
How it is all deployed
Everything described here is a single Terraform root module with in-repo modules for APIM, Cognitive Services and Cosmos DB, plus the client's shared modules for VNet, AKS, Key Vault, storage and PostgreSQL. One variable, environment, selects non-production or production and drives subscriptions, IP ranges, retention and DNS domains from a locals map.
The pipeline is GitLab CI using a shared multi-environment Terraform template. It authenticates to Azure with OIDC (also with managed identities, see my other blog post on https://ascode.nl/blog/gitlab-runners-aks/), so the pipeline has no service principal secret either, and it runs plan and apply per environment. Locally, pre-commit runs terraform fmt, tflint, terraform-docs, checkov and secret detection before anything can be committed. If you don't run pre-commit locally, the pipelien forces it and will fail if pre-commit fails. The README's resource inventory is generated by terraform-docs, which sounds like a small thing but means the documentation cannot drift from the code.
What this foundation buys the AI layer
Everything in the next three parts sits on top of this. The APIM gateway is injected into snet-apim and talks to model backends through private endpoints in snet-plink. The Function App that ingests usage runs in snet-fn with a user-assigned identity, exactly like the pods on the cluster. End users reach the frontend applications on AKS through the Application Gateway; the backend workloads on the cluster call the APIM gateway directly over the private network with an API subscription key, and never hold a model key.
If you take one thing from this post, let it be this: the AI-specific parts of an AI Landing Zone are maybe thirty percent of the work. The rest is a properly built, identity-first, private-by-default platform, and if you skip it, you end up with an AI gateway that has a public IP and a connection string in an app setting, which is not much better than the whatever number of OpenAI resources you started with.
Part 3 is where it gets AI-specific: the gateway itself, and how one APIM instance becomes a single front door for OpenAI and Mistral.
If you are planning a similar platform and want to compare notes, or would like to know what it takes to get this running in your own estate, connect with me on LinkedIn or reach out via ascode.nl.